Over on the public CFML Slack group, several people have reported that recent security patches for Adobe ColdFusion (both 2023 and 2025) have broken the use of \U and \L constructs in regular expression replacements. These flags were used, respectively, to uppercase or lowercase the subsequent character sequences (often represented by back-references to captured groups):
\u- uppercase the next letter.\U- uppercase the rest of sequence (or up to\E).\l- lowercase the next letter.\L- lowercase the reset of the sequence (or up to\E).
With the recent security updates, these flags are now treated as normal escape sequences. Meaning \u becomes the literal u and \L becomes the literal L. Both of which (now surprisingly) show up in the resultant string.
I don't use these very often, especially since they only work in the POSIX-based regular expressions, not the Java ones; but, they do show up from time-to-time. In fact, my current implementation of ucFirst() — my polyfill of the Lucee-only built-in function — is using them.
In the following demonstration of ucFirst(), I'm capturing word characters at delimited boundaries; and then I'm using the \u flag to uppercase those captured characters in the resultant string:
<cfscript>

	writeDump([
		ucFirst( "hello" ),
		ucFirst( "hello my friend" ),
		ucFirst( "hello my friend", true ),
		ucFirst( "les états-unis" ),
		ucFirst( "les états-unis", true ),
	]);

	/**
	* I capitalize the first letter of the given string. If "all", I capitalize the first
	* letter of each word within the string. A word is classified as any alpha characters
	* that come after whitespace, dot, dash, or parenthesis.
	*/
	private string function ucFirst(
		required string input,
		boolean doAll = false
		) {

		if ( doAll ) {

			return input.reReplace( "(^|[\s.()-])(\w)", "\1\u\2", "all" );

		}

		return input.reReplace( "^(\w)", "\u\1" );

	}

</cfscript>
This was working fine a few weeks ago; and now when I run this in Adobe ColdFusion 2025 update 14, I get the following output:
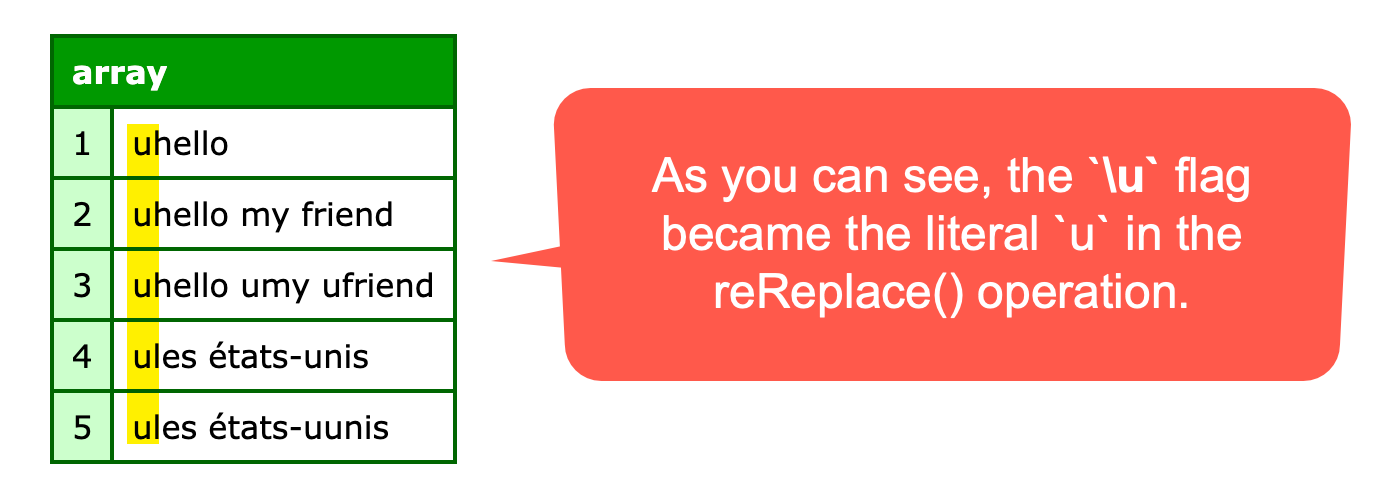
As you can see, the \u in my reReplace() call is interpreted as the escape sequence for a literal value, not the uppercase flag. My current implementation of ucFirst() is broken.
Now, as luck would have it, I recently wrote about how Adobe ColdFusion's enhanced Java integration — as of 2025 update 8 — allows me to pass CFML closures into Matcher::replaceAll(). This gives me the ability to execute CFML code on a per-match basis. Which means that I can replace my \u flag with an explicit .ucase() call.
Using the Pattern / Matcher mechanics makes this approach more verbose; but, it gets around the broken feature. And by "upgrading" my regular expression engine from the POSIX to the Java, I'm able to use the (?U) flag — not to be confused with the \U flag — to get the \w character class to match on international letters as well.
<cfscript>

	writeDump([
		ucFirst( "hello" ),
		ucFirst( "hello my friend" ),
		ucFirst( "hello my friend", true ),
		ucFirst( "les états-unis" ),
		ucFirst( "les états-unis", true ),
	]);

	/**
	* I capitalize the first letter of the given string. If "all", I capitalize the first
	* letter of each word within the string. A word is classified as any alpha characters
	* that come after whitespace, dot, dash, or parenthesis.
	*/
	private string function ucFirst(
		required string input,
		boolean doAll = false
		) {

		if ( input.len() <= 1 ) {

			return input.ucase();

		}

		if ( ! doAll ) {

			return ( input[ 1 ].ucase() & input.right( -1 ) );

		}

		// Now that we're using Java Patterns, we're going to use the UNICODE flag `(?U)`
		// to get the lower case letters (`\p{Lower}`) to match on foreign characters.
		return new java( "java.util.regex.Pattern" )
			.compile( "(?U)(^|[\s.()-])\p{Lower}" )
			.matcher( input )
			.replaceAll( ( matcher ) => matcher.group().ucase() )
		;

	}

</cfscript>
For each match, my closure is now being used to calculate the replacement value. And, in this context, the matcher.group() value is the entire matched sequence ending in the \p{Lower} character. Running this Adobe ColdFusion 2025 code gives me the following output:
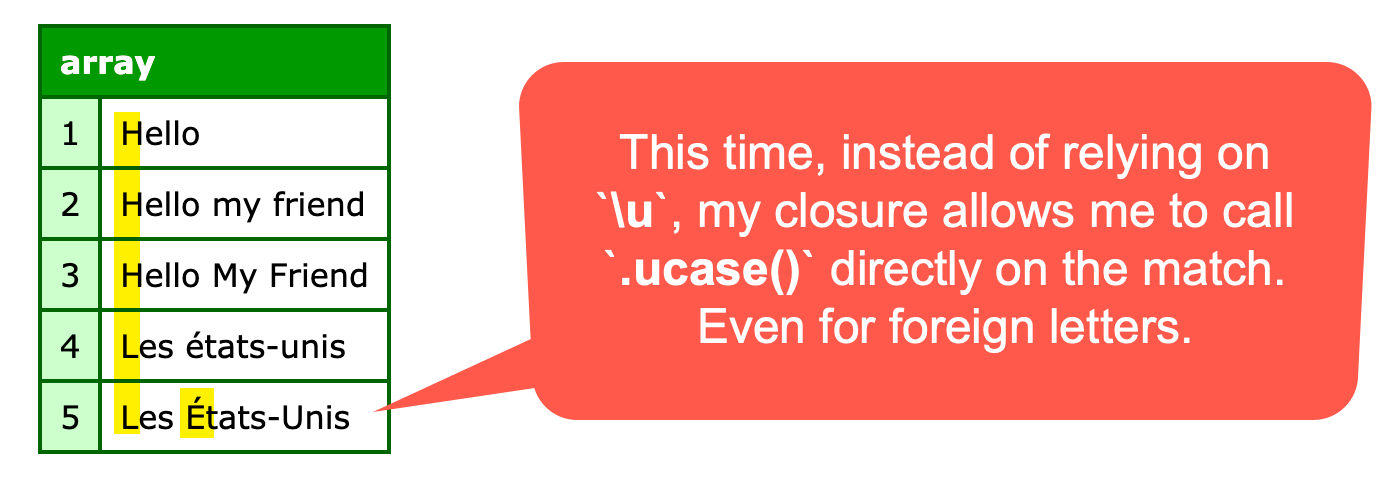
Works like a charm. It's more heavy-handed and requires more moving parts. But, those moving parts give me better regular expression pattern support and more explicit control over how the uppercase is being applied.

Reader Comments
Post A Comment — ❤️ I'd Love To Hear From You! ❤️
Post a Comment →